Jisoo Park
I am a Ph.D. student in the Computer Vision and Machine Learning (CVML) Lab at Chung-Ang University, advised by Junseok Kwon. I completed my M.S. in Artificial Intelligence and B.S. in Computer Science and Engineering at the same institution.
My research focuses on audio-visual learning, where vision and hearing (the two primary senses humans rely on to perceive the world) meet in a single model. I am broadly interested in understanding and generating multimodal signals that combine these modalities, and I am recently extending this line of work to brain signals to explore deeper, more integrated forms of multimodal fusion.
CV / Email / Google Scholar / GitHub / LinkedIn
News
- 2026.09 One paper has been accepted to NeurIPS 2026.
- 2026.08 Visiting researcher at Imperial College London (iBUG group), advised by Dr. Stavros Petridis.
- 2026.06 Two papers have been accepted to ECCV 2026.
- 2025.09 Visiting researcher at University of Birmingham (NEURECA group), advised by Prof. Hyojin Park.
- 2025.08 One paper has been accepted to ASRU 2025.
- 2024.12 Started a research internship at Korea Electronics Technology Institute (KETI).
- 2024.12 One paper has been accepted to AAAI 2025.
- 2024.09 One paper has been accepted to ECCV 2024 Workshop.
Publications
* denotes equal contribution. † denotes corresponding author.
For a complete list, see my Google Scholar profile.
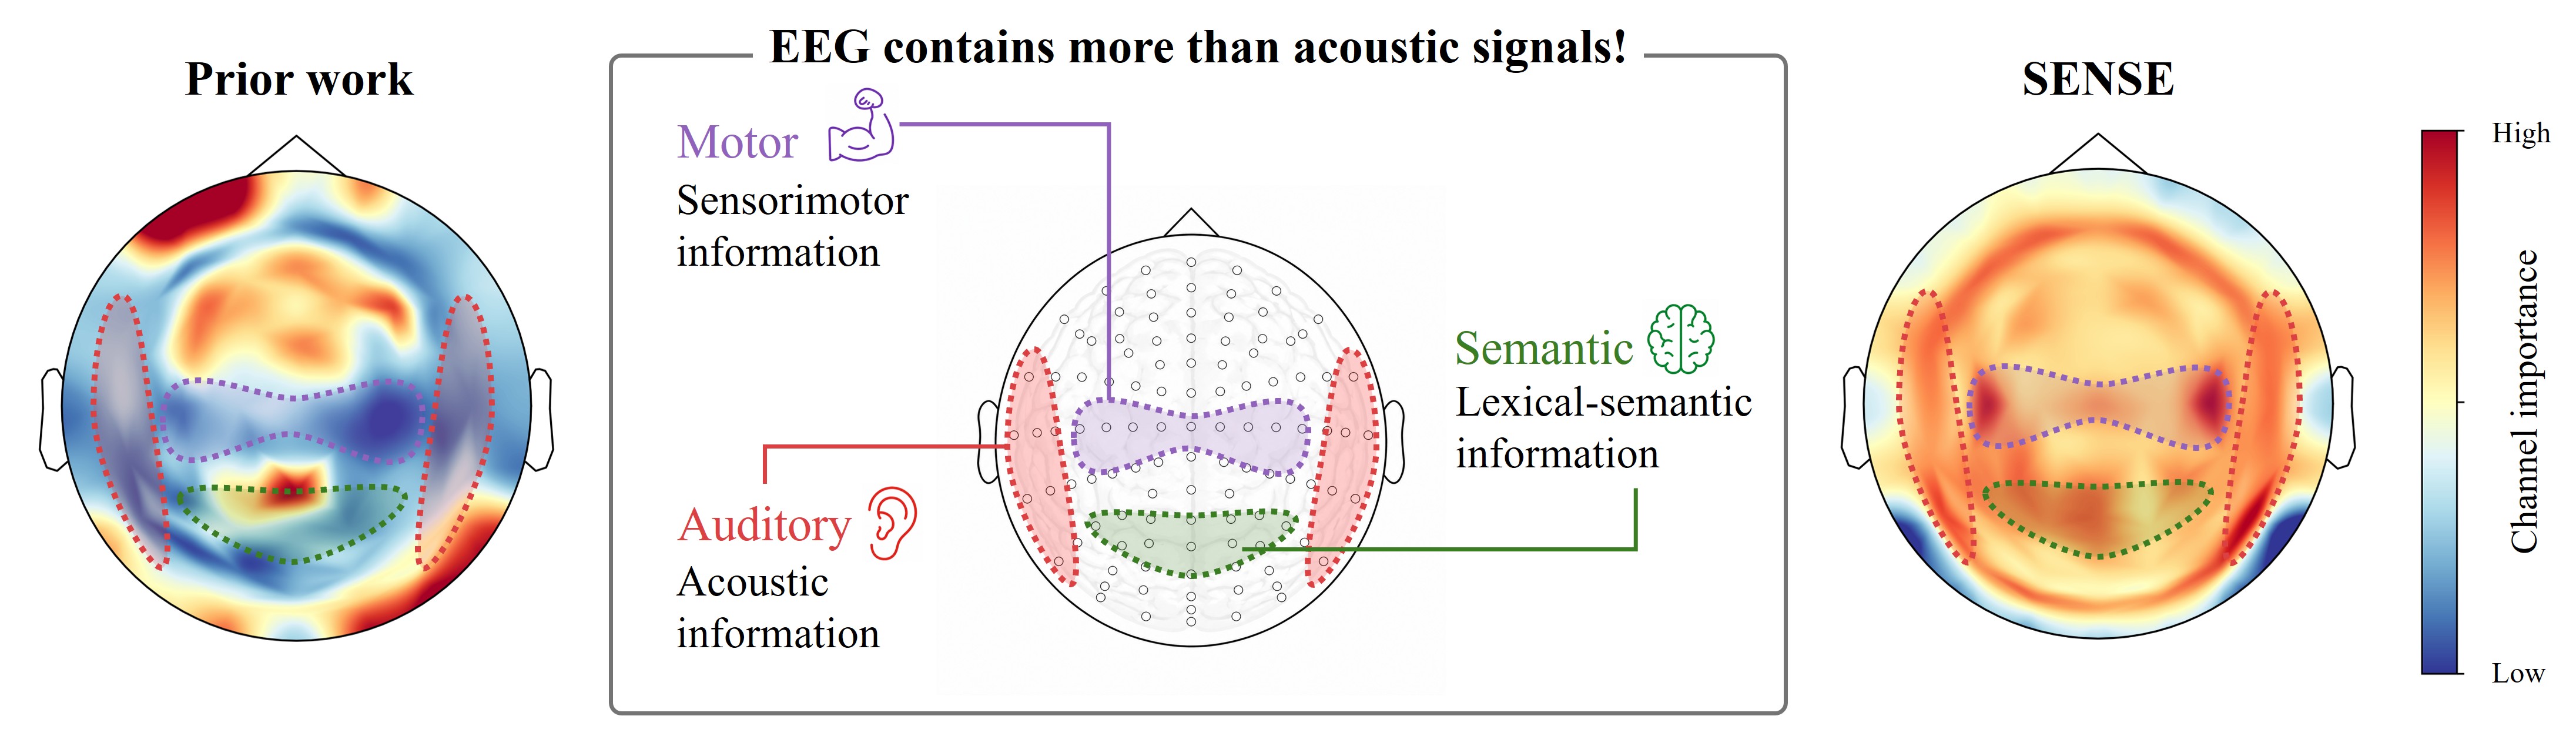
SENSE: Semantic Neural Speech Synthesis from Brain Dynamics via Spatial Graph Encoding
The Conference on Neural Information Processing Systems (NeurIPS), Sydney, Australia, 2026
Work done during a research visit to the University of Birmingham.
Reframes EEG-to-speech as semantic rather than acoustic reconstruction, pairing a graph encoder over electrode geometry with semantic-space alignment.
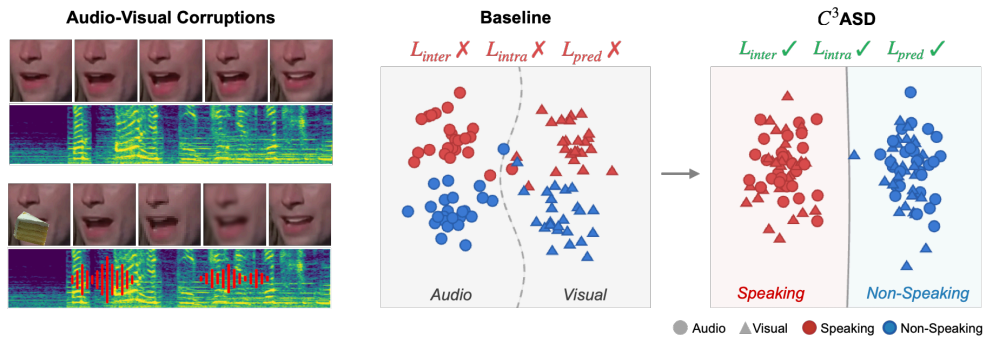
C³ASD: Multi-Level Consistency-Driven Representation Learning for Robust Active Speaker Detection
The European Conference on Computer Vision (ECCV), Malmö, Sweden, 2026
Enforces audio-visual consistency at the embedding, sequence, and prediction levels to keep active speaker detection robust under noise, occlusion, and modality corruption.
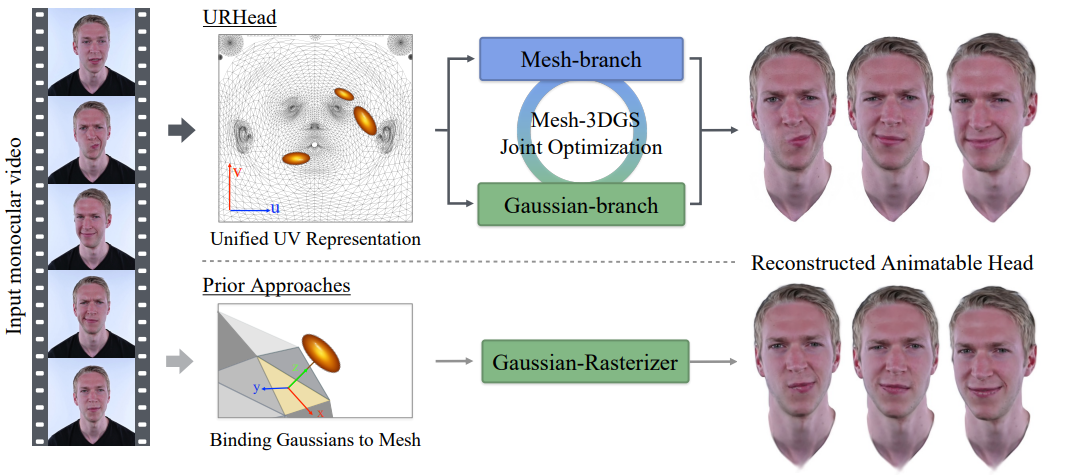
URHead: A Unified UV-Space Representation for Joint Mesh–3DGS Optimization in Head Avatars
The European Conference on Computer Vision (ECCV), Malmö, Sweden, 2026
Unifies mesh and 3D Gaussian representations in a shared UV space and jointly optimizes them, so head avatars stay both fully controllable and photorealistic.
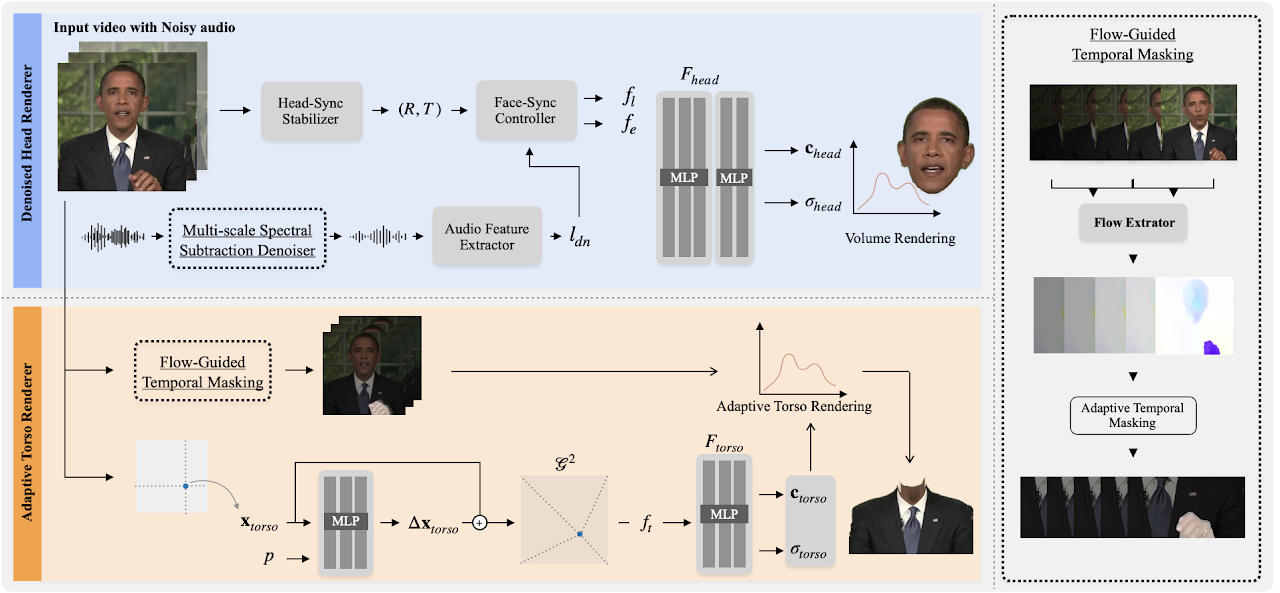
WildTalker∞: Pushing the Limits of 3D Talking Portrait Synthesis in Unconstrained Environments
IEEE Transactions on Audio, Speech and Language Processing (T-ASLP), vol. 34, pp. 1259–1271, 2026
Synthesizes robust 3D talking portraits in the wild via flow-guided temporal masking for transient visual artifacts and multi-scale spectral subtraction for noisy audio. (extended version of our ECCV-W WildTalker)
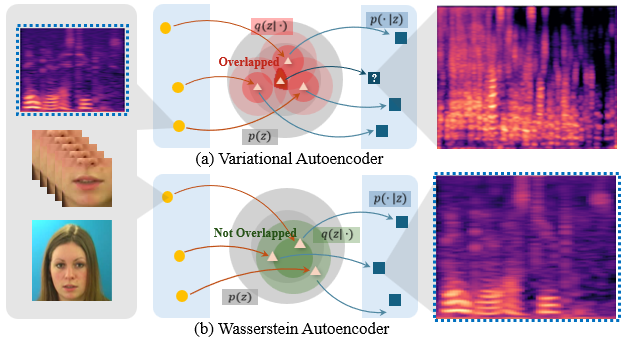
Lightweight Wasserstein Audio-Visual Model for Unified Speech Enhancement and Separation
IEEE Automatic Speech Recognition and Understanding Workshop (ASRU), Honolulu, Hawaii, USA, 2025
A lightweight, unsupervised audio-visual model that unifies speech enhancement and separation, using lip and face cues with Wasserstein regularization and no paired clean data.
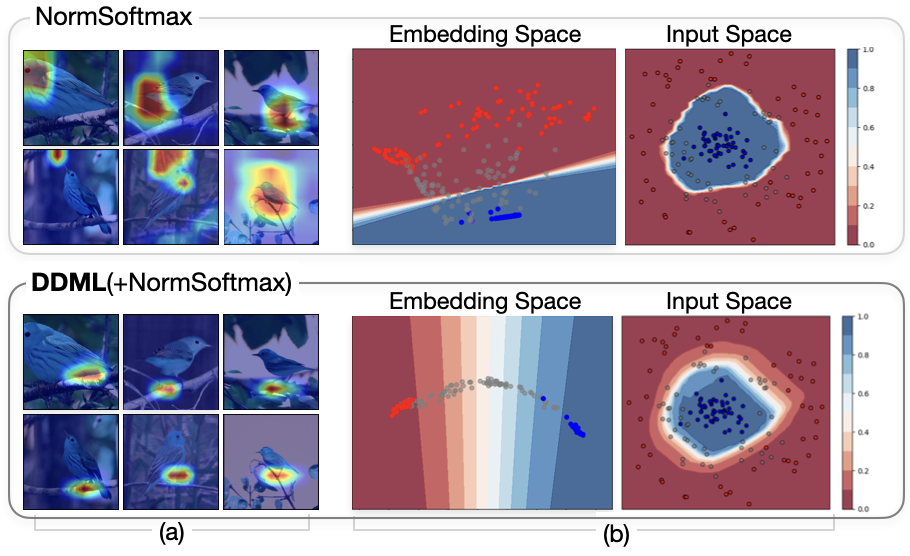
Deep Disentangled Metric Learning
The 39th Association for the Advancement of Artificial Intelligence (AAAI), Philadelphia, Pennsylvania, USA, 2025
Adds class-agnostic, information-bottleneck regularization to proxy-based metric learning, disentangling features to improve generalization to unseen classes.
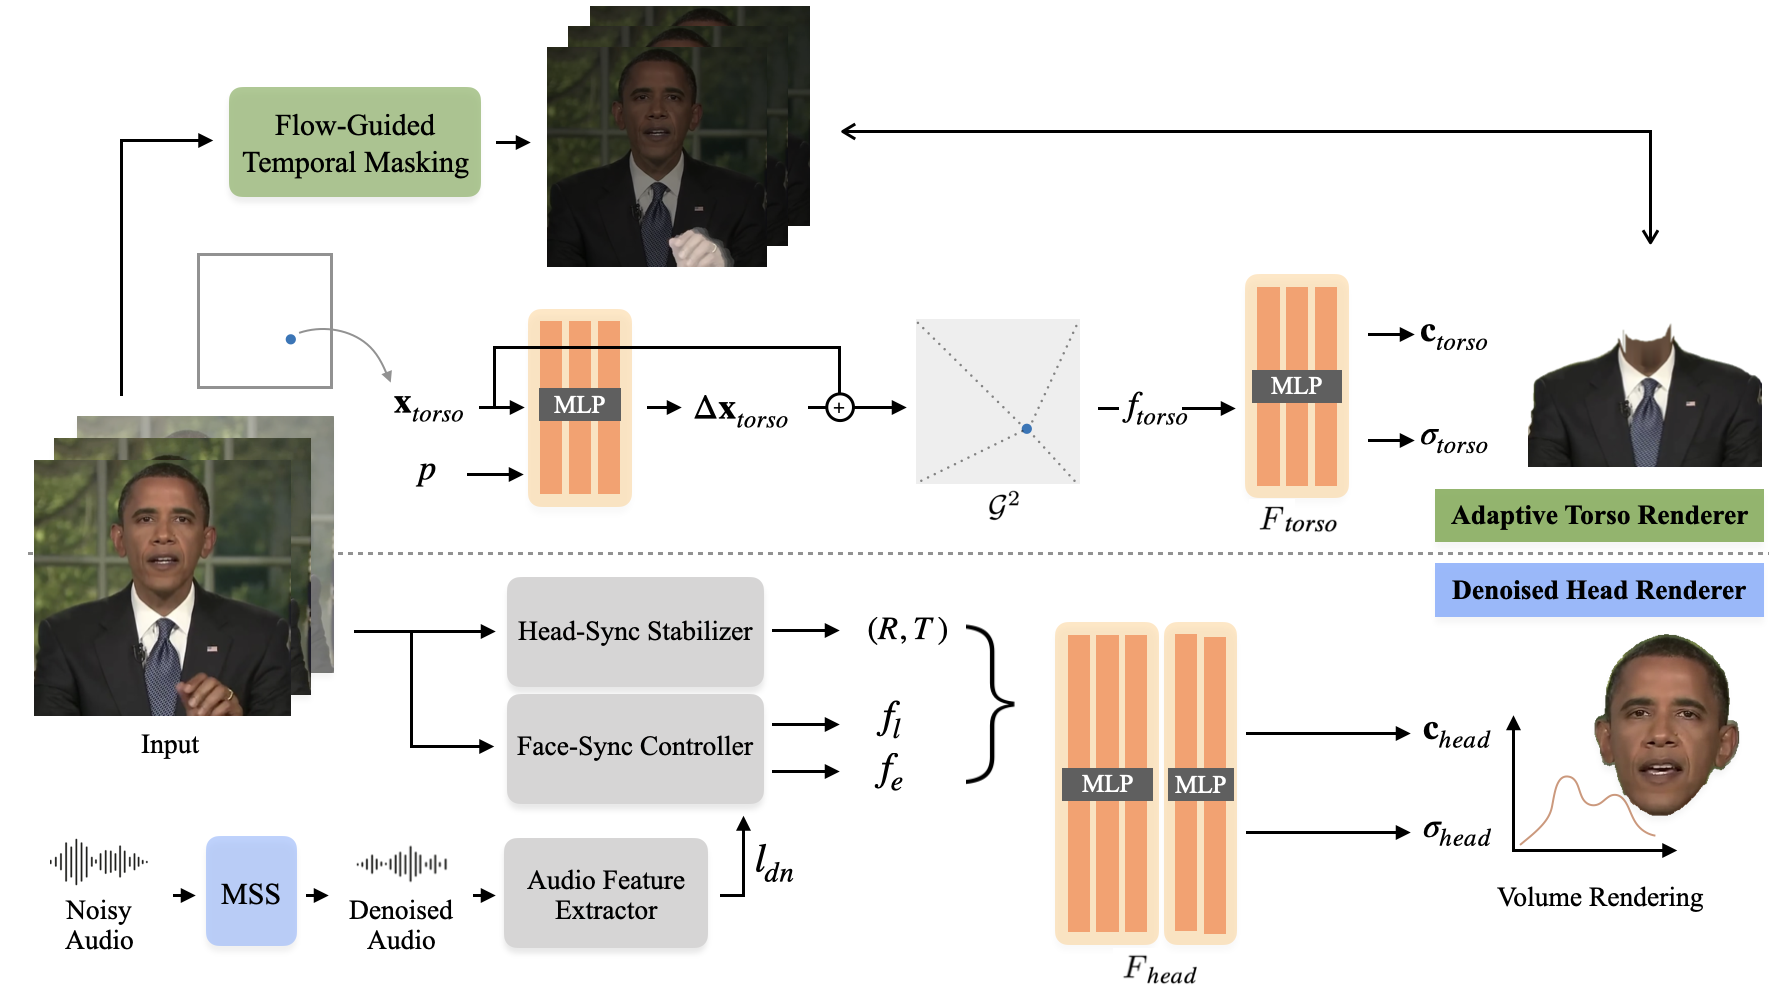
WildTalker: Talking Portrait Synthesis in the Wild
The 18th European Conference on Computer Vision Workshop (ECCV Workshop) — 3D Modeling, Reconstruction, and Generation in the Wild, Milano, Italy, 2024
Generates natural, lip-synced 3D talking portraits in noisy, dynamic real-world conditions through flow-guided temporal masking and multi-scale spectral subtraction.
Experience
Visiting Researcher
Imperial College London · London, UK
Aug. 2026 –
- iBUG group, advised by Dr. Stavros Petridis
Visiting Researcher
University of Birmingham · Birmingham, UK
Sep. 2025 – Nov. 2025
- NEURECA group, advised by Prof. Hyojin Park
- Worked on Semantic speech synthesis from EEG signals
Research Intern
Korea Electronics Technology Institute (KETI) · Seongnam, Korea
Dec. 2024 – Mar. 2025
- Intelligent Image Processing Research Center
- Worked on Generalized deepfake detection
Scholarships & Fellowships
- AI Seoul Tech Research Support Program, Seoul Future Foundation (2026–2027)
- IITP Applied AI Fellowship (University of Toronto), Ministry of Science and ICT, Korea (2024)
Patents
- Jinhee Park, Jisoo Park, Dagyeong Na, and Junseok Kwon. KOR Patent 10-2024-0096387, “Deep Metric Learning Method for Similarities between Images Introducing Class-agnostic Features” (July 2024).